
SAGE-CREH: adaptive subagent coordination and skills
Updated Sep 13, 2026
Preprint: manuscript without confirmed peer review.
Abstract
A fifth architecture, the same twelve tasks and 216 new runs: comparing completion, tokens, time and skill distribution with code and data.
How should subagents be organized?
Reproducible code and data: SAGE-CREH repository on GitHub.
This research compares coordination architectures and skill distribution, not different models. Who solves? Who checks? When does delegation add value? Which instructions does each worker actually need?
The previous version studied four patterns: sequential, parallel, hierarchical and reflexive. This update adds a fifth architecture implemented at CREH Labs, SAGE-CREH, and reruns the original controls on the same tasks with the same model. The article expands its review from nine to twelve arXiv papers.
SAGE-CREH achieved 23/24 strict successes (95.8%), averaging 1,765 tokens and 7.34 seconds per task. It used 47.2% fewer tokens than sequential, 49.3% fewer than parallel, 61.1% fewer than hierarchical and 30.2% fewer than reflexive.
This was the highest observed strict score, but it did not win under every criterion. Normalizing only the SQL envelope gave sequential and reflexive 24/24; SAGE and the original single agent reached 23/24. The single agent needed fewer resources: 1,160 tokens and 4.62 seconds on average. The latency difference between SAGE and parallel was small and uncertain.
SAGE without delegation reached 21/24 with 1,110 tokens: coordination added 59.1% more tokens and two successes in this sample. Two failures of that control were JSON envelopes with an extra key, which the predefined SQL normalization does not remove. Within SAGE’s own traces, five initial candidates were corrected: three SQL-contract reviews and two adjudications involving dependencies and selection. Its only final failure was counting seven events instead of eight on T02, despite correct monetary totals.
The practical reading is conditional: SAGE offers a useful tradeoff when strict answers are required, at lower consumption than fixed teams. If SQL normalization is allowed and cost is paramount, this sample favors the single agent; if observed normalized completion is paramount, reflexive is cheaper and faster than sequential. Completion-difference intervals do not establish general superiority.
The fifth architecture: SAGE-CREH
SAGE-CREH combines skill selection with conditional delegation. A deterministic coordinator recognizes public task structure, loads relevant instructions and selects one of two paths:
- Direct path: one solver proposes an answer. If it satisfies the output contract and reports no specific unresolved issues, execution ends. Otherwise a verifier reviews the proposal.
- Subagent path: for predefined structural complexity, two independent solvers work concurrently. One solves the full problem; the other pays particular attention to constraints, dependencies and tie breakers. Matching valid candidates without unresolved issues avoid an integrator; disagreement triggers an adjudicator.
The policy activates two solvers for graphs with at least eight nodes and any node with two or more predecessors, and for selection with at least ten items, forbidden pairs and prerequisites. These rules were fixed before replication. The gate validates format; it does not know the correct answer. Agreement does not guarantee that both agents are right.
The adjudicator receives original data and proposals, never evaluator feedback. There is no access to reference answers, SQL execution against hidden databases, or retry-until-correct loop. The name identifies this local composition; it does not claim to invent adaptive routing.
Five architectures, side by side
| Architecture | Implemented organization | Calls per task |
|---|---|---|
| Sequential | Extraction, solving and integration, one stage after another. | 3 |
| Parallel | Two simultaneous complementary specialists and a fixed integrator. | 3 |
| Hierarchical | Supervisor plans one or two assignments, workers execute, results are integrated. | 3–4 |
| Reflexive | Proposal, critique and revision upon objections; at most two rounds. | 2–5 |
| SAGE-CREH | Direct path or two independent solvers; adjudication only when triggered. | 1–3 |
A one-call single-agent reference is also retained. All use the same model; changing a role does not change its weights. SAGE’s parallel path introduces selective redundancy, whereas the original parallel pattern uses a fixed complementary division of responsibilities.
How skills are distributed
The catalog retains ten skills: six relevant to the problems and four distractors. SAGE identifies the interface from public task fields and supplies only the relevant instruction body. It does not resend the full description catalog on each call.
| Task family | Skill responsibility |
|---|---|
| Ledger | Revisions, status and monetary sums. |
| Calendar | Time zones and common availability. |
| Dependencies | Precedence, earliest starts and critical path. |
| Selection | Budget, coverage, incompatibilities and tie breakers. |
| Memory | Confirmations, deletions, scopes and inheritance. |
| SQL | Read-only queries, aggregation and edge cases. |
Agents on the same task can receive the same skill while taking different roles. All retain the complete public input. This evaluates a closed-world interface adapter, not semantic skill retrieval for open-ended conversations.
Benchmark: same task, model and evaluator
The new wave contains 216 runs, 510 calls and 707,090 observed tokens. There were 0 infrastructure or protocol errors. Development resource use is reported separately.
The twelve original tasks are repeated twice in nine conditions: four architectures, a single agent, SAGE and three ablation controls. Each condition has 24 runs. Ten problems use exact-match grading; each of the two SQL queries is tested against three databases hidden from agents.
GPT-5.6 Luna uses low reasoning effort and at most 1,536 output tokens per call, including reasoning. Controls retain their original prompts. Order is randomized by task and repetition, with one condition at a time and at most two simultaneous within-flow calls. The model identifier and configuration are preserved.
Replication results
| Configuration | Strict | SQL norm. | Tokens | s/task | Calls |
|---|---|---|---|---|---|
| Single agent | 19/24 | 23/24 | 1,160 | 4.62 | 24 |
| Sequential | 20/24 | 24/24 | 3,343 | 12.47 | 72 |
| Parallel | 19/24 | 22/24 | 3,480 | 7.69 | 72 |
| Hierarchical | 18/24 | 22/24 | 4,532 | 11.13 | 96 |
| Reflexive | 20/24 | 24/24 | 2,527 | 9.54 | 54 |
| SAGE-CREH | 23/24 | 23/24 | 1,765 | 7.34 | 38 |
Tokens and seconds are per-task means; calls are condition totals. Time includes network and coordination, excluding the evaluator. Tokens sum every input and output: cache and reasoning are already included, never added twice.
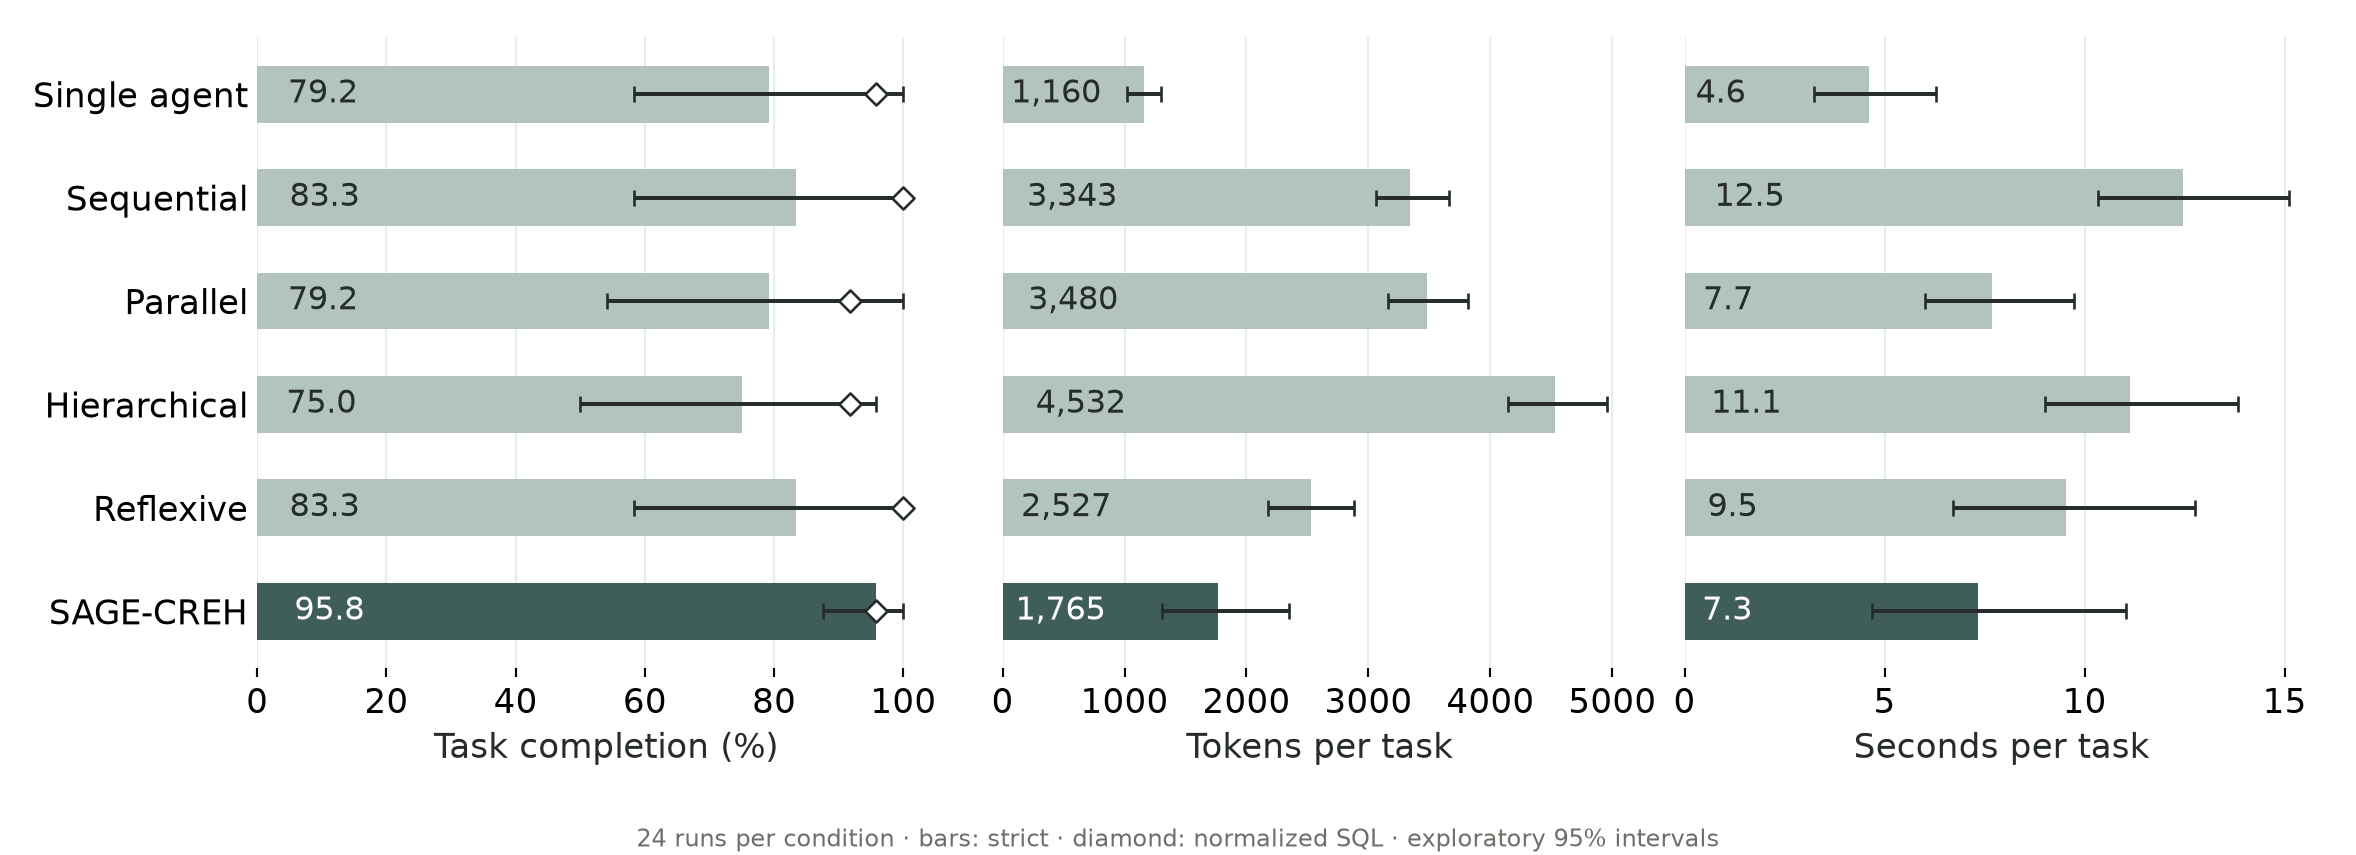
The strict column requires the original JSON envelope. Secondary SQL norm. only wraps a raw SQL string into the requested nested field and applies the same evaluator: it changes no query and repairs no solution. This sensitivity was identified in v1 and predefined as a secondary metric for v2. Better formatting must not be mistaken for better reasoning.
Paper intervals use 10,000 paired task-cluster draws, retaining both repetitions. There are twelve distinct tasks, not 216 independent problems. Intervals are exploratory, and ceilings do not establish perfect reliability.
Is the difference coordination or instruction loading?
| Configuration | Strict | SQL norm. | Tokens | s/task | Calls |
|---|---|---|---|---|---|
| Hierarchical | 18/24 | 22/24 | 4,532 | 11.13 | 96 |
| Hierarchy + 10 skills | 20/24 | 22/24 | 8,578 | 10.62 | 96 |
| SAGE-CREH | 23/24 | 23/24 | 1,765 | 7.34 | 38 |
| SAGE without delegation | 21/24 | 21/24 | 1,110 | 5.93 | 24 |
| SAGE + 10 skills | 22/24 | 22/24 | 2,966 | 6.38 | 34 |
SAGE without delegation uses the same proposer and instruction payload, but never calls another agent. SAGE with ten skills keeps the policy while supplying every instruction body. The original hierarchy pair also measures that loading cost.
Against the original patterns, SAGE changes topology, prompts and catalog exposure. These ablations help distinguish effects; attributing every difference exclusively to coordination would be incorrect.
Observed SAGE routes: 13 direct path, 5 parallel agreement without integrator, 3 adjudication after two proposals, 3 selective review.
Development and policy selection
Two policies were tested on ten fresh instances, separate from replication: serial, 9/10, averaging 1,606.7 tokens and 9.07 seconds; parallel, 10/10, averaging 1,628.4 tokens and 8.11 seconds. Parallel was selected for higher completion under the prior rule. Development totaled 20 runs, 28 calls and 32,351 tokens.
Every attempt is retained. Selection was recorded before replication, and the architecture remained frozen throughout the 216 runs. Offline tests validate contracts, routes and accounting; their outcomes are not counted as model successes.
The success separating candidates occurred on DEV22, a calendar task where both used the same direct path without review. That variation does not demonstrate a causal effect of parallelism; selection is retained under the prior rule.
How the literature informed the design
Progressive instruction loading and the separation between skills and workers motivate context controls. The extension incorporates selective delegation from Uno-Orchestra, progress-conditioned decisions from ProgRouter, and continuation review from TROVE. These are conceptual foundations: their training is not reproduced and their scores are not presented as our results.
Scope and materials
This is an exploratory preprint without peer review. Final tasks were already known during design: this is a development-informed paired replication, not a blind generalization test. It evaluates one model, short contexts and synthetic tasks, without terminal use, browsing, multi-file programming, persistent memory or RAM measurement.
Practical selection should consider completion, tokens and waiting time together. Traces show when a revision corrected something and when it only added cost. Both waves are retained separately; historical latency is not pooled with new measurements.
- Full v2 paper in English.
- Paper v2 completo en español.
- Code, LaTeX sources, protocols and every trace.
- Workbook with all nine conditions.
- Summary CSV, per-run CSV and paired comparisons.
- Routes and corrections, SQL sensitivity and hashes.
- Historical v1 paper in English and preserved v1 data.
The package contains only synthetic data, visible answers and research materials. It includes no credentials, private conversations or private deliberation.
Sources and consulted versions
- Agent Skills for Large Language Models: Architecture, Acquisition, Security, and the Path Forward — 2602.12430v4; 2026-02-12.
- Benchmarking Multi-Agent LLM Architectures for Financial Document Processing: A Comparative Study of Orchestration Patterns, Cost-Accuracy Tradeoffs and Production Scaling Strategies — 2603.22651v1; 2026-03-24.
- CRAFT: Grounded Multi-Agent Coordination Under Partial Information — 2603.25268v2; 2026-03-26.
- EvoAgent: An Evolvable Agent Framework with Skill Learning and Multi-Agent Delegation — 2604.20133v3; 2026-04-22.
- Swarm Skills: A Portable, Self-Evolving Multi-Agent System Specification for Coordination Engineering — 2605.10052v2; 2026-05-11.
- When Does Hierarchy Help? Benchmarking Agent Coordination in Event-Driven Industrial Scheduling — 2605.13172v1; 2026-05-13.
- Beyond Sequential Interaction: Benchmarking Parallel Execution and Coordination for GUI Agents — 2607.22689v1; 2026-07-17.
- OrchBench: Evaluating Multi-Agent Orchestration Plans in Isolation via Deterministic Simulation — 2607.25656v1; 2026-07-28.
- Subagents vs Agent Skills: Executing Reusable Knowledge for Long-Horizon Agentic Tasks — 2609.09233v1; 2026-09-07.
- GPT-5.6 Luna Model — Documentation accessed 2026-09-13; Accessed 2026-09-13.
- Uno-Orchestra: Parsimonious Agent Routing via Selective Delegation — 2605.05007v1; 2026-05-06.
- ProgRouter: Online Progress-Guided Orchestration for Multi-Agent LLM Workflows under Quality-Cost Tradeoffs — 2608.25992v1; 2026-08-26.
- TROVE: Adaptive Agent Skill Orchestration via Trace-Grounded Route Validation and Editing — 2609.05019v1; 2026-09-04.